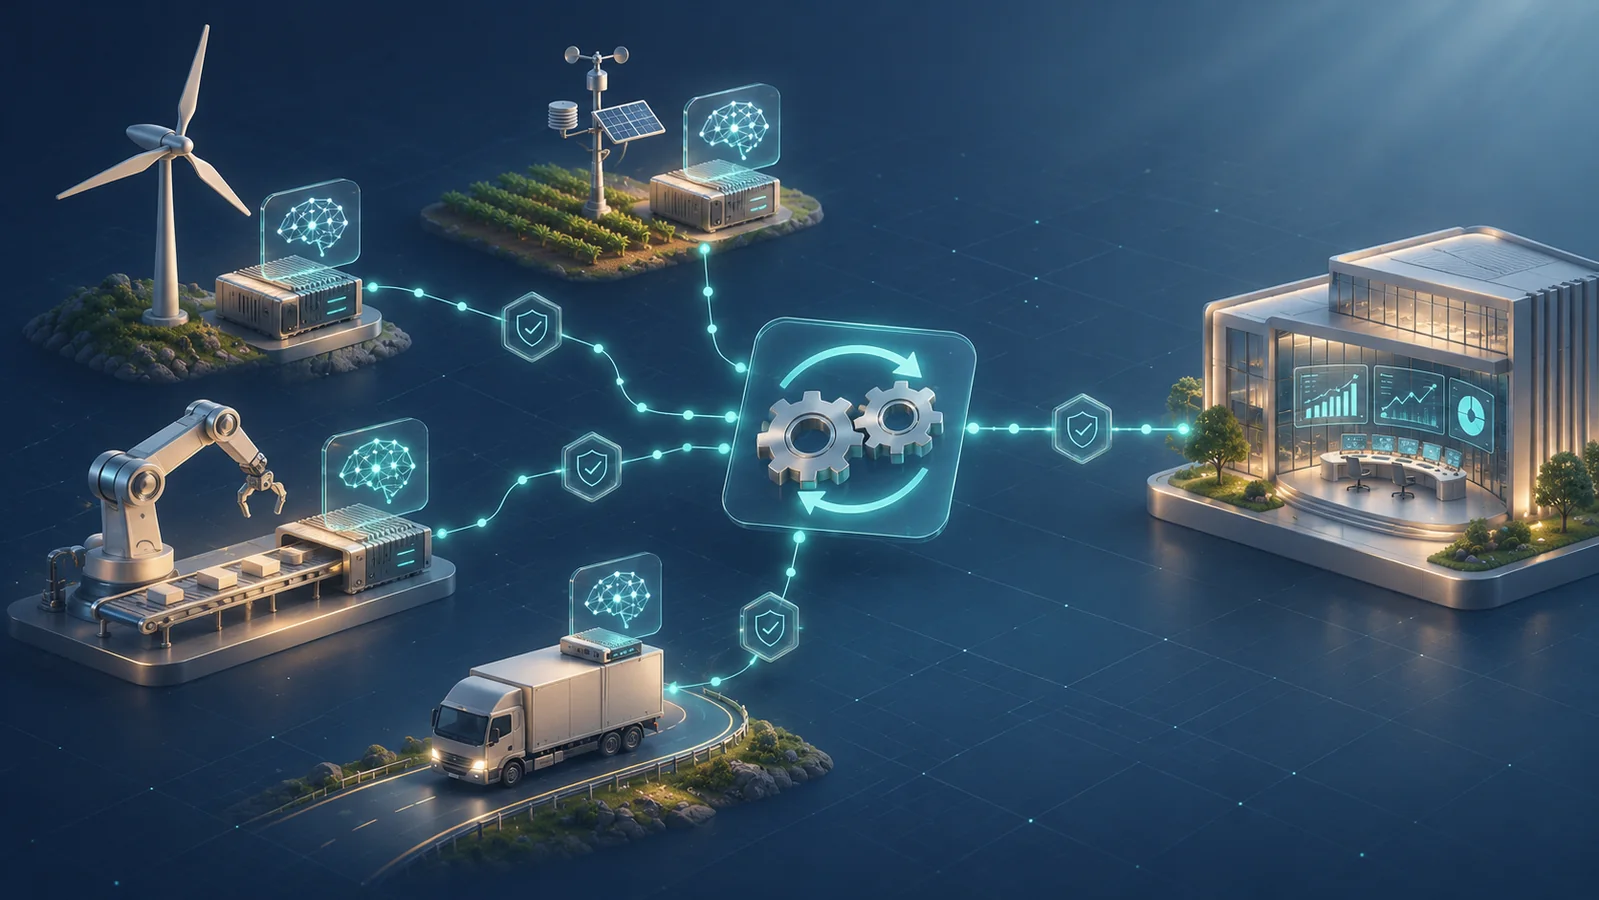
Embedded AI processes data close to sensors. Edge computing raises a synchronization challenge: how can information reach central systems without compromising reliability, security or cost efficiency? Architectures, protocols and consistency models shape these exchanges, along with their technical, regulatory and financial risks.
Introduction – An urgent need for harmonisation
In a smart factory, every machine equipped with a sensor produces several dozen megabytes of measurements per minute: temperature, vibrations, energy consumption, high-resolution images. For these streams to feed machine learning (ML) models capable of detecting anomalies in real time, data must be processed locally – to reduce latency and network traffic – while remaining accessible to a central repository where global training, governance and historical consolidation take place.
This dual requirement creates a tension: decentralising computation to benefit from edge computing, yet consolidating data to ensure a comprehensive overview. Synchronisation thus becomes the critical link that determines business value (predictive maintenance, energy optimisation, quality improvement) and regulatory compliance (GDPR, sector-specific requirements). Ignoring this issue quickly leads to data inconsistencies, network congestion or security vulnerabilities.
The choice of architecture depends on the trade-offs among available solutions and each organisation’s operational and strategic constraints.
1. Typical architecture of embedded AI at the network edge
+-------------------+          +-------------------+          +-------------------+
| Capteurs / IoT    |   ⇄      | Edge Node (GPU)   |   ⇄      | Cloud Central     |
| (données brutes)  | MQTT/CoAP| (pré‑traitement,  | gRPC/REST| (data lake, MLOps)|
+-------------------+ | inference, stockage) +-------------------+- Sensors / IoT: low-power devices generating continuous streams.
- Edge Node: server or embedded device (e.g. NVIDIA Jetson, Intel Xeon‑D) performing pre-processing, model inference and buffer storage.
- Central Cloud: data platform (data lake, warehouse), training pipelines, decision dashboard.
Friction points are located at the edge ↔ cloud interfaces:
- Limited bandwidth – particularly in remote or industrial sites where the network is shared with control systems.
- Critical latency – certain decisions must be made in under 100ms (e.g. emergency stop).
- Network variability – temporary losses, jitter, partial outages.
These constraints dictate the choice of synchronisation model presented hereafter.
2. Edge-cloud data synchronisation models
| Model | Description | Advantages | Disadvantages |
|---|---|---|---|
| Batch (offloaded) | Periodic transmission (e.g., hourly) of a batch of files or snapshots. | Simplicity, low network overhead. | High latency, risk of data loss in the event of a failure prior to the batch process. |
| Continuous Streaming | Constant stream via publish/subscribe protocols (MQTT, Kafka, AMQP). | Low latency, near real-time visibility. | Continuous bandwidth consumption, requirement for robust orchestration. |
| Opportunistic / Store‑and‑Forward | Local buffer storage; transmission initiated as soon as sufficient connectivity is detected (e.g., 4G → Wi‑Fi). | Resilience to outages, network cost optimisation. | Complexity of queue management and consistency. |
| Hybrid Edge‑Cloud Learning | Local incremental training + periodic gradient aggregation (FedAvg, FedProx). | Reduction of raw data traffic, preservation of confidentiality. | Requires a mature federated learning framework, management of model drift. |
The choice will depend on three axes: functional criteria (required latency, data volume), infrastructure constraints (available bandwidth, cost) and compliance requirements (localisation of personal or industrial data).
3. Protocols and formats suited for edge‑cloud synchronisation
3.1 MQTT – The quintessential lightweight protocol
- Characteristics: publish/subscribe, QoS 0‑2, low overhead, TLS support.
- Use case: transmission of measurements (temperature, machine status) to a central broker (e.g., EMQX, HiveMQ).
- Limitations: not designed for transporting large files (images, videos); requires a fragmentation mechanism.
3.2 gRPC + Protobuf
- Features: high-throughput RPC, compact binary serialisation, bidirectional streaming support.
- Use cases: inference calls from cloud to edge (e.g., "predict") or sending updated models ("model push").
- Limitations: requires strict TLS configuration for security, less tolerant of intermittent networks.
3.3 Apache Kafka / Redpanda
- Features: persistent distributed log, partitioning, configurable retention.
- Use cases: ingestion of massive streams (video, logs) with replay capabilities in case of loss.
- Limitations: requires a resilient cluster, more resource-intensive to deploy on modest edge nodes.
3.4 OPC‑UA (Industrial IoT)
- Features: rich object model, built-in security, TCP/HTTPS transport support.
- Use cases: interoperability with SCADA systems and programmable logic controllers (PLCs).
- Limitations: higher overhead than MQTT, implementation complexity.
3.5 Serialisation formats
| Format | Size | Compatibility | Security |
|---|---|---|---|
| JSON | + | Universal | Plain text – encryption required |
| CBOR | ++ | Compact, binary | TLS required for confidentiality |
| Protobuf | +++ | Strict binary | Integrated into gRPC, easy versioning |
The choice of protocol must be aligned with the data type (telemetry vs. media), sensitivity (PII, industrial secrets), and network constraints.
4. Consistency management and conflict resolution
When multiple edge nodes write simultaneously to the same centralised dataset, the risk of inconsistencies increases. The following strategies are commonly adopted:
- Timestamp-based versioning (Lamport timestamps) – each update carries a logical counter; the most recent version prevails.
- CRDT (Conflict‑free Replicated Data Types) – data structures designed to converge automatically (e.g., G‑Counter, LWW‑Register). Ideal for metadata and configuration states.
- Simplified Two‑Phase Commit (2PC) – used when a transaction must be atomic between edge and cloud (e.g., updating a critical setting parameter).
- Merge‑on‑Read – conflicts are resolved during reading by the central server, applying business rules (priority to origin site, average aggregation, etc.).
These mechanisms are often accompanied by an observability layer (event logs, replication metrics) to quickly detect drifts and trigger automated reconciliation procedures.
5. Security, Privacy and Compliance
| Aspect | Risk | Mitigation Measure |
|---|---|---|
| Mutual Authentication | Unauthorised access to edge nodes | Mutual TLS (mTLS) with revocable X.509 certificates |
| Data integrity in transit | Tampering or event injection | HMAC-SHA256 signatures, sequence numbers to detect replay attacks |
| Confidentiality of sensitive data | Exposure of PII or industrial secrets | End-to-end encryption (AES‑GCM) prior to transmission; encrypted local storage at the edge |
| Key lifecycle management | Prolonged compromise | Automatic key rotation via a KMS service (e.g. AWS KMS, Azure Key Vault) |
| Compliance (GDPR, IEC 62443) | Non-compliance with localisation or traceability requirements | Data tagging with provenance metadata, immutable audit log (blockchain‑style or WORM) |
A crucial point is anomaly detection within the synchronisation flow. Integrating a detection engine based on Machine Learning (e.g. time series models) enables immediate alerting in the event of suspicious activity (sudden bursts, anomalous data).
6. Use case: predictive maintenance in Industry 4.0
Context
An automotive production plant has 250,000 sensors distributed across three geographical sites. Each sensor sends 10 kB/s of measurements (vibration, temperature). The objective is to anticipate electric motor failures to reduce unplanned downtime.
Deployed architecture
| Level | Component | Role |
|---|---|---|
| Edge | NVIDIA Jetson AGX Xavier + Docker‑Compose | Execution of the classification model (CNN) for inference, local score aggregation, one-hour buffer storage. |
| Transport | MQTT + TLS (QoS 1) | Publication of 'anomaly' alerts and aggregated metrics every 5 minutes. |
| Cloud | Azure Synapse + Azure ML Pipelines | Batch ingestion of raw data overnight, global model retraining, distribution of updated models via gRPC. |
| Consistency Management | CRDT LWW‑Register for threshold settings | Ensures that every site maintains the same configuration following an update. |
Results (internal study example)
- 30% reduction in MTTR (Mean Time To Repair) due to real-time alerting.
- 70% decrease in network traffic compared to a centralised architecture (raw data remains on-site; only aggregated metrics are transferred).
- GDPR compliance ensured: no personal data is collected; event logs are encrypted and retained for 90 days.
This scenario illustrates how the combination of edge inference and opportunistic streaming balances operational performance with cost control.
7. Economic Evaluation and Decision Criteria
| Criterion | Key Question | Evaluation Method |
|---|---|---|
| Total Cost of Ownership (TCO) | What is the acquisition cost of edge hardware versus the increase in network traffic? | CAPEX + OPEX analysis over 3-5 years, including licensing, energy, and maintenance. |
| Return on Investment (ROI) | What business value (reduction in downtime, quality improvement) is generated? | Efficiency KPIs (MTTR, OEE), calculation of financial gain versus project cost. |
| Scalability | Does the chosen model support the addition of new sensors or sites without a major redesign? | Simulated load tests, projection of required bandwidth. |
| Operational Complexity | What level of expertise is required to manage the platform (DevOps, security)? | Mapping of internal skills, training requirements, or outsourcing needs. |
| Compliance and Governance | Do the flows comply with legal requirements (GDPR, ISO 27001)? | Compliance audit, verification of location metadata processing. |
| Resilience | Does the system continue to operate in the event of partial network loss? | Failure scenarios, failover testing. |
A weighting matrix allows decision-makers to assign an overall score to each considered architecture and justify the choice to stakeholders.
8. Key Considerations – What a Decision-Maker Needs to Remember
8.1 Latency vs. Bandwidth
Do not confuse latency (response time) with throughput. A streaming-oriented architecture can offer low latency but consume significant bandwidth, which is not viable over satellite or 3G links.
8.2 Model Lifecycle Management
Continuous AI deployment (MLOps) requires an automated pipeline to push new versions to edge nodes. Without this, there is a risk of obsolete models generating false positives/negatives.
8.3 Physical Device Security
Edge nodes are often deployed in unsecured environments (factories, vehicles). Hardening (secure boot, TPM) and firmware integrity monitoring are essential to prevent physical compromises.
8.4 Data Governance
Every synchronised data point must be accompanied by metadata (origin, timestamp, sensitivity level). This simplifies audits and ensures compliance with the GDPR principle of data minimisation.
8.5 Vendor Lock-in
Proprietary protocols or managed services can create dependencies that are difficult to exit. Preference should be given to open standards (MQTT, gRPC, OPC‑UA) and cloud-agnostic solutions.
9. Operational Conclusion
Data synchronisation between embedded AI at the edge and central systems is no longer a simple transport issue: it is an architectural discipline involving the definition of consistency models, the selection of appropriate protocols, the implementation of end-to-end security, and the establishment of a data governance framework.
The organisations that succeed will be those capable of:
- Precisely mapping their flows (volume, criticality, sensitivity) in order to select the optimal trade-off between batch, streaming, or hybrid approaches.
- Standardising protocols to guarantee interoperability and avoid technological lock-in.
- Integrating resilience by design – store‑and‑forward, CRDT, automated reconciliation – to support the network outages inherent to industrial environments.
- Automate model lifecycle management (MLOps) to ensure the edge always benefits from the latest improvements without heavy manual intervention.
- Make security-by-design a priority, incorporating mTLS, hardware encryption, and regular audits.
By following these principles, companies will transform their sensors into sources of actionable intelligence both locally (for responsiveness) and globally (for strategic vision), while controlling costs and regulatory requirements.
10. Priority Recommendations
| # | Concrete Action | Owner | Timeline |
|---|---|---|---|
| 1 | Conduct a flow audit (type, volume, sensitivity) at each edge site. | IT Architect / CIO | Q1 2025 |
| 2 | Deploy an MQTT-TLS platform with QoS ≥ 1 for critical telemetry. | Ops / Security Team | Q2 2025 |
| 3 | Implement a CRDT versioning framework for shared parameters. | DevOps / CIO | Q3 2025 |
| 4 | Establish an MLOps pipeline (model CI/CD) with automated push via gRPC. | Data Science Lead | Q4 2025 |
| 5 | Formalise the encryption policy for data in transit and at rest (AES-GCM + KMS rotation). |