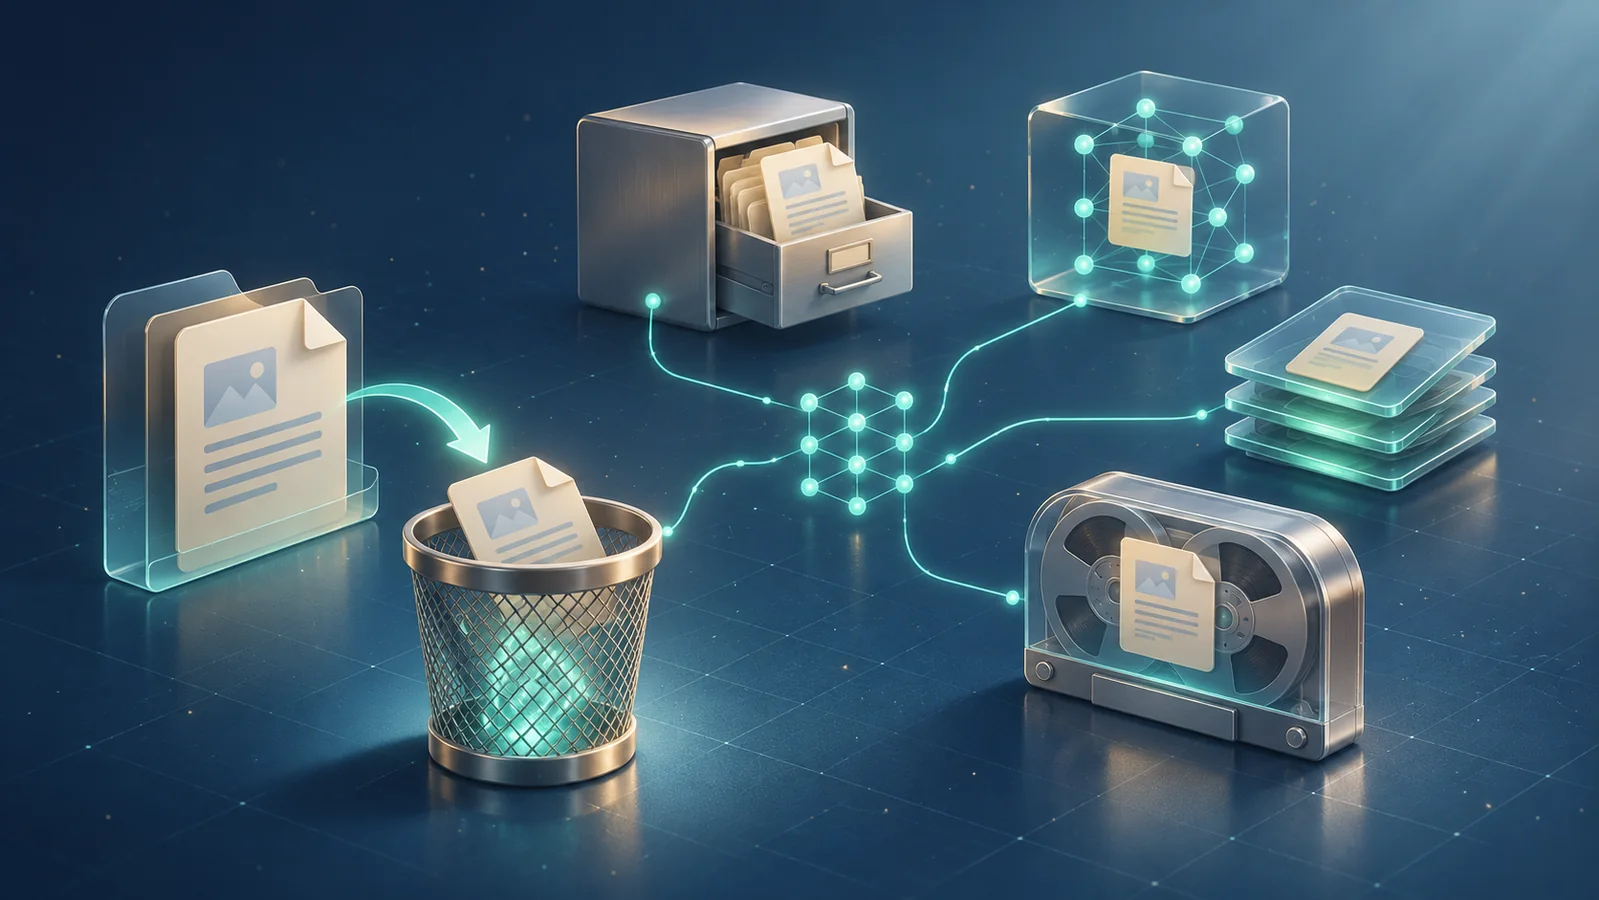
Organisations often ask: "Is deleting the source file enough?" The same document may also remain in primary storage, an AI vector index, several cache layers, or a backup chain. These copies complicate complete erasure, which must also account for GDPR and CCPA requirements, residual risks, and operating costs.
Introduction – When deletion becomes a multidimensional challenge
Imagine a financial services company needing to remove the bank statements of a client who has exercised their right to erasure. The PDF file is deleted from the file server; however, the same document still appears in:
- a vector index powering a semantic search engine based on language models,
- several caches (Redis, CDN, application cache) used to accelerate user query responses,
- a backup chain (daily snapshots, cold archives on tape or in the cloud).
The compliance officer asks: 'Will the authorities verify that the document has disappeared everywhere?'. The answer depends on a nuanced understanding of data flows, legal requirements, and the technical capabilities of each component. We provide here an exhaustive analysis to enable executives, architects, and security teams to make informed decisions.
1. Typical architecture of a modern document management system
| Level | Primary function | Common technologies |
|---|---|---|
| Primary storage | Durable persistence of the raw file | S3, Azure Blob, NAS, databases (PostgreSQL LOB) |
| Semantic indexing | Content transformation into vectors for AI search | Milvus, Pinecone, Weaviate, FAISS |
| Application cache / CDN | Latency reduction and server load mitigation | Redis, Memcached, CloudFront, Akamai |
| Backup & archiving | Disaster recovery, retention compliance | EBS Snapshots, Azure Backup, Glacier, Veeam |
Each layer has its own lifecycle: ingestion, update, expiration. The deletion of a file does not automatically trigger the purge of metadata or derived copies.
2. Legal framework – The right to erasure and its technical implications
| Text | Primary Obligation | Technical Scope |
|---|---|---|
| GDPR Art. 17 (Right to Erasure) | Delete data "without undue delay" | Requires the deletion of all copies, including those in caches and backups, unless legal exceptions apply |
| CCPA §1798.105 | Obligation to "delete any personal data collected" | Implies updating backup systems to prevent subsequent restoration |
| NIST SP 800-88 Rev.1 (Media Sanitization) | Secure erasure methods based on the medium | Provides guidelines for the permanent deletion of physical and logical media |
Regulators now expect organisations to demonstrate full traceability of erasure, including indirect systems (caches, indices). A simple "delete" at the primary storage level is generally deemed insufficient.
3. Residual Persistence Risks
- Volatile Caches – Even after the source file is deleted, content may remain in memory until the TTL (time-to-live) expires or an explicit invalidation has been triggered.
- Vector Index – Generated vectors remain stored in specialised databases; they are not automatically linked to the original file and can be reused for semantic search.
- Incremental Backups – Snapshots capture the full state of the disk at a given point in time. A post-snapshot deletion does not erase previous versions, which may be restored.
- Cold Archiving – Glacier-type solutions or tapes are often retained for several years for compliance reasons; recovering an old backup can reintroduce the file.
These scenarios create an exposure surface where a malicious actor (or even an internal audit) could recover data that was purportedly deleted.
4. Secure Deletion Methods – Beyond simple DELETE
4.1 Logical vs Physical Deletion
| Technique | Description | Advantages | Limitations |
|---|---|---|---|
| Logical deletion (soft delete) | Updates a flag in the database; the file remains physically present | Fast, minimal performance impact | Data remains recoverable until the storage medium is reused |
| Physical erasure (shredding) | Overwriting disk sectors with random patterns (e.g., dd if=/dev/urandom) | Compliant with NIST recommendations for SSD/HDD | Complex to implement on modern file systems, risk of SSD wear |
| Crypto-shredding | Deletion of the encryption key for an encrypted file | Instantaneous, no additional write operations | Requires all data to be encrypted at rest |
Crypto-shredding is currently the most effective method for ensuring the immediate unavailability of copies, provided that encryption is applied granularly (per file or per object).
4.2 Cache Invalidation
- Short TTL – Configure a lifespan tailored to compliance requirements (e.g., 30 days) to ensure data expires quickly.
- Proactive purging via API – Most Redis, Memcached, or CDN systems offer targeted PURGE/FLUSH commands. Integrating these calls into the erasure workflow ensures synchronisation.
- Cache-aside pattern – The application first reads from the cache but writes only to the database; upon deletion, it explicitly removes the cache entry.
4.3 Vector Index Cleaning
- Vector deletion by ID – Engines such as Milvus or Pinecone allow for the removal of a vector via its unique identifier.
- Periodic re-indexing – In environments where bulk deletion is rare, a full reconstruction of the index (e.g., every 30 days) eliminates residuals.
- Expiration metadata – Store the erasure date in the vector's metadata field and filter queries to exclude expired entries.
5. Backup and Retention Management
5.1 Differentiated Retention Strategies
| Level | Recommended Policy |
|---|---|
| Primary Backup (daily) | Retain for 7 days; apply a pruning process that removes objects marked as deleted prior to the next snapshot |
| Medium-term Archiving | 30 days with encryption and key separation; implement a key invalidation procedure for sensitive folders |
| Legal Archiving (long term) | Retain according to legal requirements (e.g., 6 years) but de-identify non-essential data via pseudonymisation or tokenisation |
5.2 Operational erasure process in the backup
- Marking the file as 'to-purge' within the metadata database.
- Triggering a cleanup job that scans recent snapshots and removes the object from archives before the next retention cycle.
- Encryption key rotation for already archived copies; deleting the key renders the data unreadable, compliant with the principle of crypto-shredding.
These steps require orchestration via an orchestrator (e.g., Airflow, Azure Data Factory) to ensure consistency across different systems.
6. Use Case – Deletion of a bank statement within an AI platform
Context
A French neobank offers its customers a semantic search engine for their documents (invoices, contracts). The data is:
- Stored in Amazon S3 with SSE-KMS encryption,
- Indexed in Milvus hosted on EKS,
- Cached via Redis Elasticache,
- Backed up daily using AWS Backup (EBS snapshot) and archived on Glacier.
The customer requests the deletion of all statements from April 2023 following a dispute.
Technical Workflow
| Step | Action | Tool / API |
|---|---|---|
| 1. Marking | Update documents table (deleted_at = now()) | PostgreSQL |
| 2. S3 Deletion | Delete objects via DeleteObject and revoke the associated KMS key | AWS SDK |
| 3. Redis Invalidation | UNLINK keys corresponding to IDs | Redis CLI / Elasticache API |
| 4. Milvus Cleanup | delete_entity_by_id for each linked vector | Milvus Python SDK |
| 5. Backup Pruning | Airflow job that iterates through EBS snapshots from day D-1, deletes marked objects, and rotates the KMS key | AWS CLI + Boto3 |
| 6. Glacier Archiving | If copies already exist, revoke the encryption key (crypto-shredding) | AWS KMS |
Result
Upon execution, no vectors or cache entries remain recoverable; snapshots containing the file are purged prior to their expiration. This enables the bank to provide a certificate of erasure compliant with GDPR.
7. Key Considerations – What to monitor
Box: Key Considerations
| Domain | Risk | Mitigation |
|---|---|---|
| Cache | Persistence until TTL expiration | Configure short TTLs and automate purges via webhook |
| Vector index | Orphaned vectors not associated with a deleted file | Implement a cleanup policy based on deleted_at metadata |
| Backup | Accidental restoration of a snapshot containing the file | Integrate deletion filters into restoration scripts and apply crypto-shredding to encryption keys |
| Encryption | Loss of the encryption key prior to complete erasure | Use a Key Management Service (KMS) with scheduled rotation and audit logging |
| Legal compliance | Conflict between legal retention requirements and the right to be forgotten | Define a data classification matrix to apply the appropriate rules (e.g., sensitive data vs legal archiving) |
8. Technical and economic constraints
- Orchestration cost – Implementing a workflow that synchronises deletion, cache purging, and backup cleanup involves development time and licensing costs (orchestrator, monitoring).
- Performance impact – Immediate purge calls can increase service latency during mass erasure peaks. A compromise consists of scheduling purges outside of peak load hours.
- Third-party reliability – SaaS services (e.g., Pinecone) sometimes offer limited APIs for selective deletion, forcing a complete index rebuild, which can be resource-intensive.
- Regulatory evolution – The legal framework evolves rapidly (e.g., the proposed European "Data Act"). Organisations must plan periodic reviews of their erasure processes.
9. Operational recommendations
Key takeaways for decision-makers
- Adopt the "defence-in-depth erasure" principle – Logical deletion + crypto-shredding for every layer.
- Integrate the purging of caches and indices into the erasure workflow via automated APIs, rather than relying solely on manual procedures.
- Implement key governance (KMS) to enable the rapid invalidation of access to encrypted copies stored within backups.
- Define differentiated retention policies based on data sensitivity and legal requirements, incorporating automated pruning processes.
- Document and audit every stage of the erasure process (logging, evidence) to satisfy GDPR/CCPA audit requests.
Conclusion – Towards True Data Disappearance
Deleting a file from primary storage is no longer sufficient to meet compliance and security requirements in modern architectures. Residual persistence in caches, vector indices, and backups creates an exposure surface that can be exploited by malicious actors or flagged during an audit. A holistic approach — combining proactive purging, crypto-shredding, granular key management, and retention orchestration — ensures 'complete erasure' while managing operational impacts.
Organisations that integrate these practices from the outset (privacy by design) reduce their legal risks, strengthen customer trust, and prepare their infrastructure for evolving regulatory requirements.
Priority Recommendations
| Priority | Action |
|---|---|
| 1 | Implement crypto-shredding across all stored objects (per-object encryption). |
| 2 | Deploy a purge orchestrator that synchronises S3 deletion, Redis invalidation, and Milvus deletion via API. |
| 3 | Review cache TTL policies to ensure they do not exceed 24 hours in high-sensitivity environments. |
| 4 | Implement an automated pruning process for snapshots prior to their final retention. |
| 5 | Document the erasure workflow and conduct semi-annual audit reviews. |
References
[1] Regulation (EU) 2016/679 of the European Parliament and of the Council of 27 April 2016 – full text of the GDPR, Art. 17 'right to erasure'. Available at: https://eur-lex.europa.eu/legal-content/FR/TXT/?uri=CELEX%3A32016R0679 (accessed 22 July 2026).
[2] California Consumer Privacy Act (CCPA) – Section 1798.105, official text, California Legislative Information. Available at: https://leginfo.legislature.ca.gov/faces/codes_displaySection.xhtml?lawCode=CIV§ionNum=1798.105 (accessed 22 July 2026).
[3] National Institute of Standards and Technology (NIST) Special Publication 800-88 Revision 1, 'Guidelines for Media Sanitization', August 2014. Available at: https://nvlpubs.nist.gov/nistpubs/SpecialPublications/NIST.SP.800-88r1.pdf (accessed 22 July 2026).
[4] ENISA – “Data protection and privacy in cloud services”, technical guide, 2022. Available at: https://www.enisa.europa.eu/publications/data-protection-and-privacy-in-cloud-services (accessed 22 July 2026).
[5] Milvus Documentation – Delete Entities, version 2.3.0, Apache Milvus. Available at: https://milvus.io/docs/delete_entities.md (accessed 22 July 2026).
[6] AWS Backup – Best practices for data protection, Amazon Web Services, 2023. Available at: https://docs.aws.amazon.com/backup/latest/devguide/best-practices.html (accessed 22 July 2026).
[7] Redis Documentation – UNLINK command, version